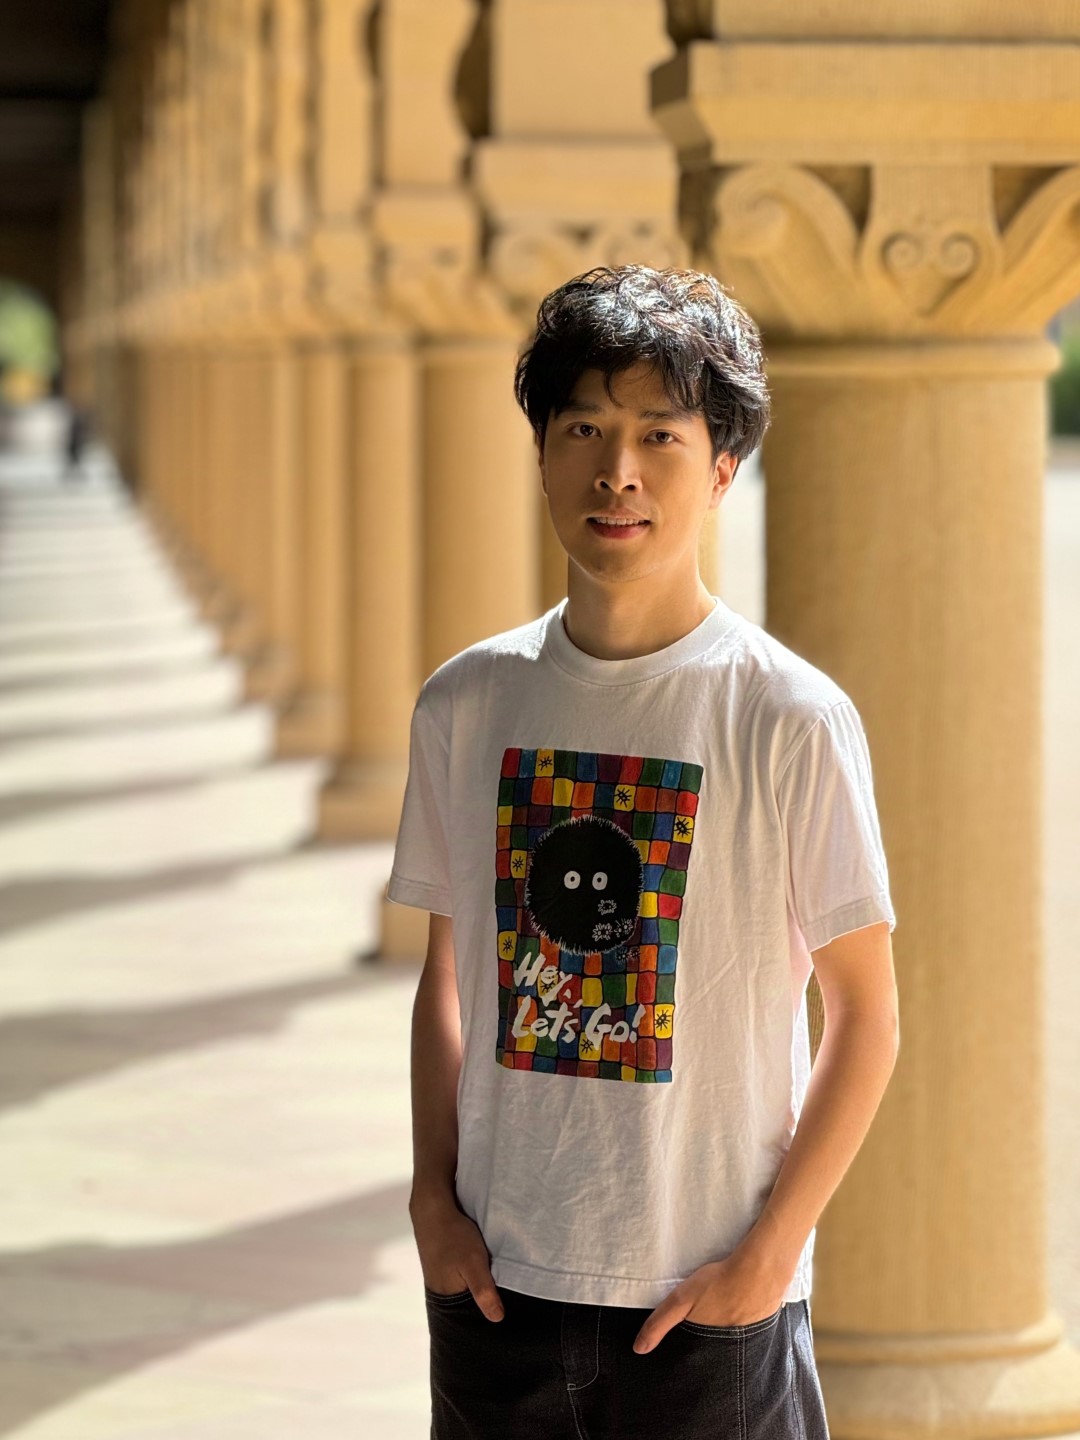
Zehan Zheng | 郑泽涵
💫About Me
I am currently a second-year CS Ph.D. student at CCVL Lab of Johns Hopkins University advised by Bloomberg Distinguished Professor Alan L. Yuille. Before this, I obtained my master’s and bachelor’s degree at Tongji University.
My research interests mainly focus on 3D Computer Vision, including Reconstruction/Generation, VLMs, World Models and Embodied AI. During my master’s program, I conducted research at Generalist Embodied AI Lab of Tongji University and advised by Prof. Guang Chen. In 2022, I was a research intern at OpenDriveLab of Shanghai AI Laboratory advised by Prof. Hongyang Li. In 2024, I have been a visiting student at SU Lab of UC San Diego advised by Prof. Hao Su, where I spent a wonderful time in La Jolla.
I’m open to any collaboration opportunity, please feel free to drop me an email📬!
🔥News
[2026/09] 🎉 One paper was accepted by NeurIPS 2026 (Evaluations & Datasets Track).
[2026/06] 🎉 One paper was accepted by ECCV 2026.
[2026/01] 🎉 One paper was accepted by ICLR 2026.
[2025/11] 🎉 One paper was accepted by WACV 2026.
[2025/09] 🎉 One paper was accepted by NeurIPS 2025.
[2025/09] Started my CS Ph.D. at Johns Hopkins University, advised by Prof. Alan L. Yuille.
[2024/12] Invited Talk at Princeton University. [slides]
[2024/12] Invited as a Reviewer for ICML.
[2024/09] 🎉 Two papers were accepted by NeurIPS 2024.
[2024/08] Invited as a Reviewer for ICLR.
[2024/05] Invited as a Reviewer for NeurIPS.
[2024/02] 🎉 One paper was accepted by CVPR 2024.
[2024/01] Invited as a Reviewer for ECCV.
[2023/11] Invited as a Reviewer for CVPR.
[2023/05] Invited as a Reviewer for ICCV.
[2023/02] 🎉 One paper was accepted by CVPR 2023.
[2022/07] 🎉 One paper was accepted by ECCV 2022 (Oral, top 2.7%).
📝Publications
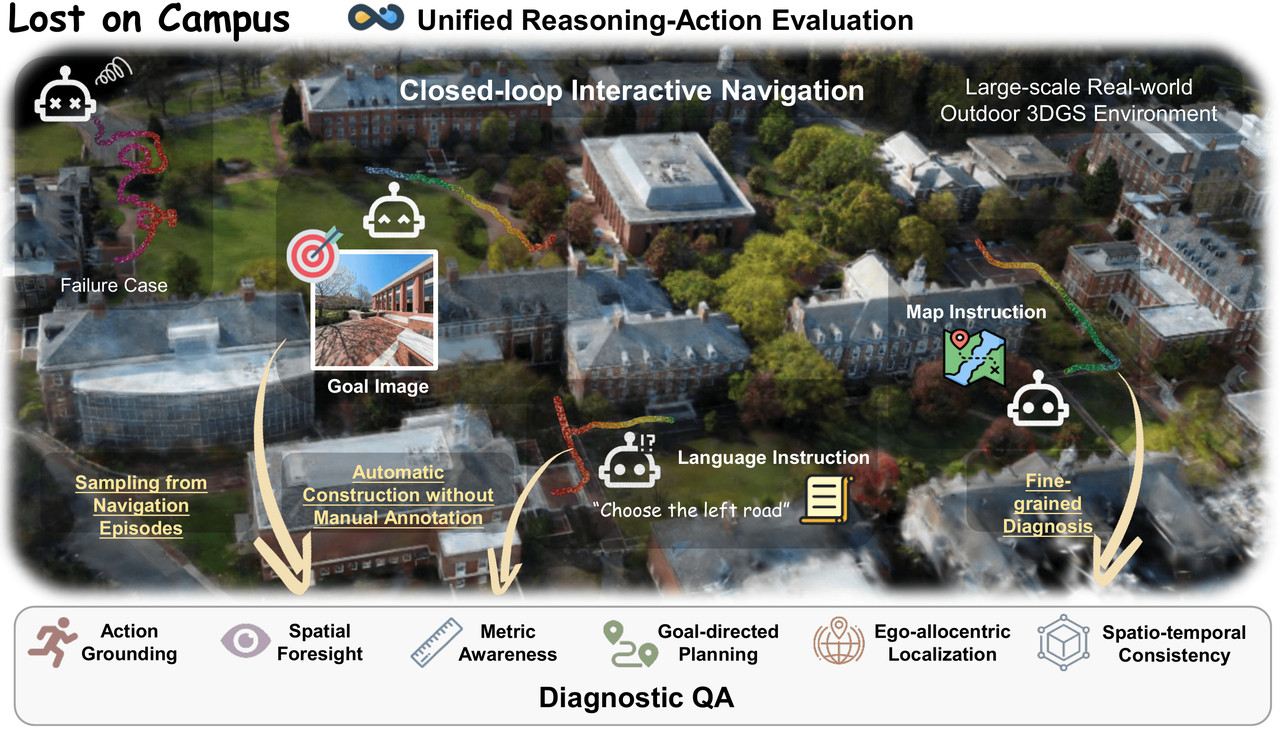
Lost on Campus: Evaluating Embodied Spatial Reasoning of Vision-Language Models in the Wild
Zehan Zheng*, Yanyuan Chen*, Deming Li, Yutao Tang, Jianwen Xie, Alan Yuille, Jieneng Chen, Cheng Peng
NeurIPS, 2026 (Evaluations & Datasets Track)
[Project Page] | Paper, Code & Dataset (Coming Soon)
Benchmark for embodied spatial reasoning of VLMs in large-scale real-world outdoor 3DGS environments, which unifies closed-loop interactive navigation with diagnostic QA to probe six fundamental spatial reasoning capabilities.
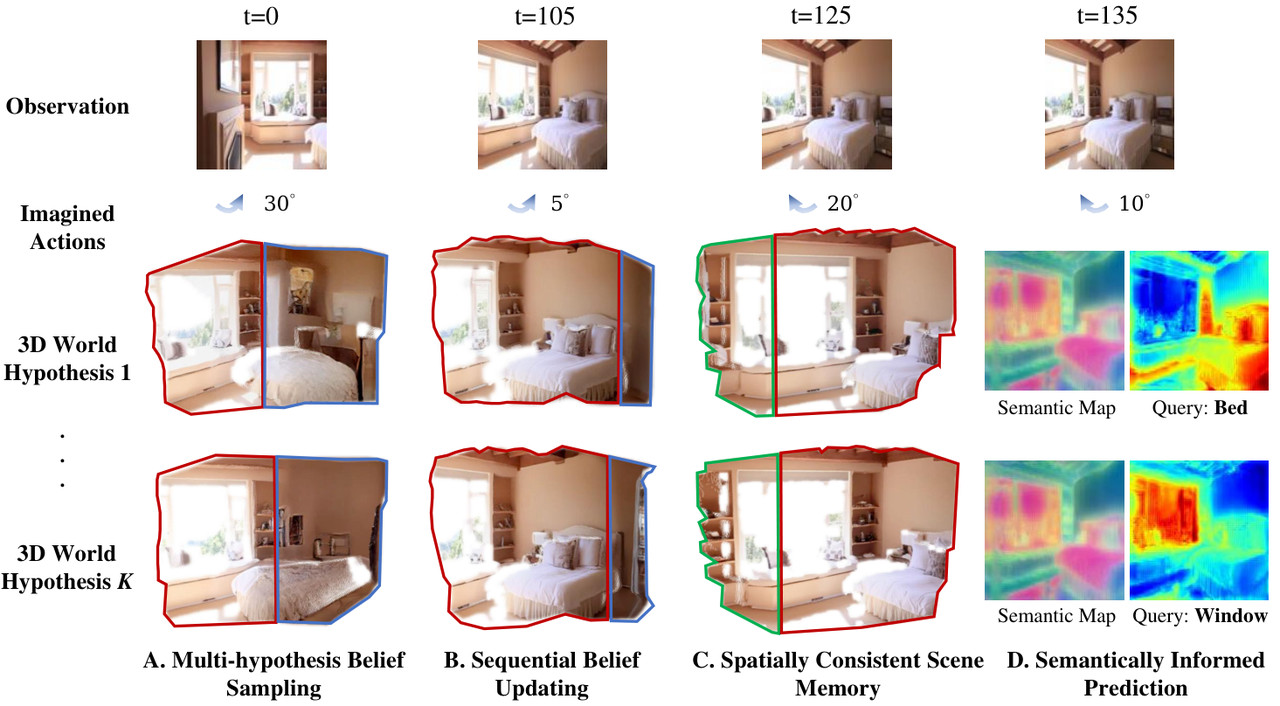
3D-Belief: Embodied Belief Inference via Generative 3D World Modeling
Yifan Yin∗, Zehao Wen∗, Jieneng Chen, Zehan Zheng, Nanru Dai, Haojun Shi, Suyu Ye, Aydan Huang, Zheyuan Zhang, Alan Yuille, Jianwen Xie, Ayush Tewari, Tianmin Shu
arXiv, 2026
[Paper] | [Code] | [Project Page] | [Data & Models]
Generative 3D world model that infers explicit 3D beliefs about unobserved regions from partial egocentric observations and updates them online, supporting multi-hypothesis imagination and belief-guided embodied planning.
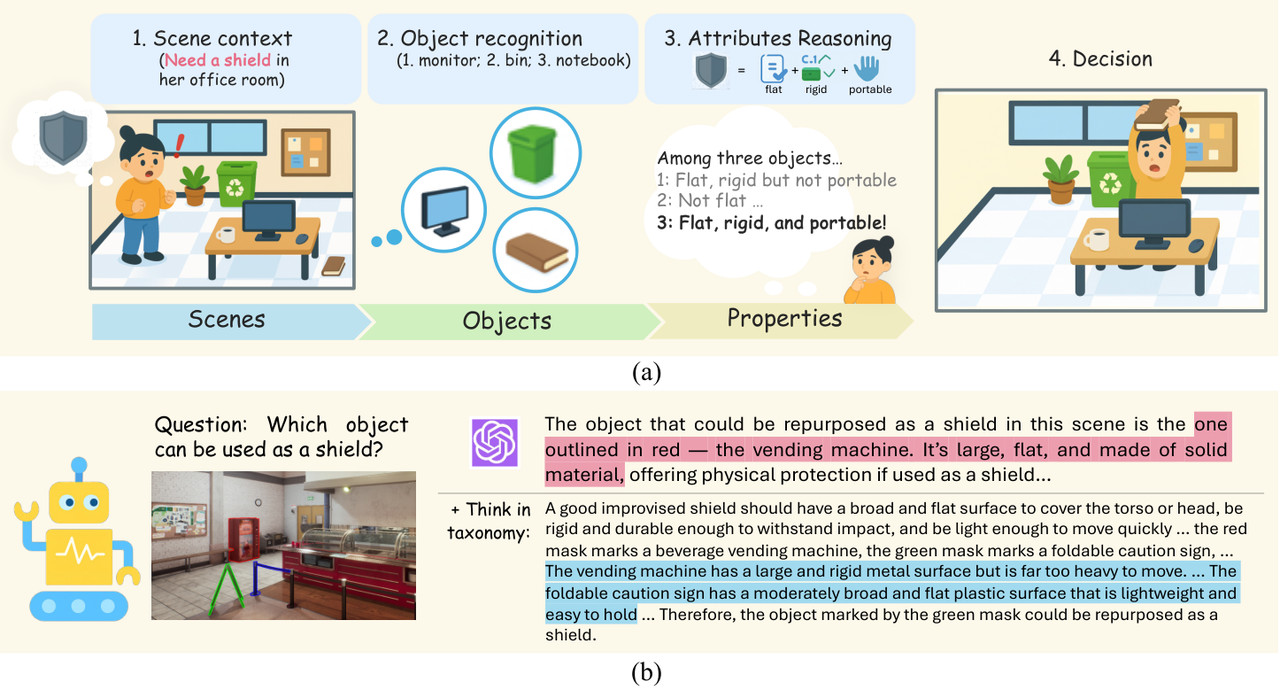
PercepTax: Benchmarking Physical Intelligence through Cross-Property Reasoning in Vision-Language Models
Jonathan Lee∗, Xingrui Wang∗, Jiawei Peng, Luoxin Ye, Zehan Zheng, Tiezheng Zhang, Tao Wang, Wufei Ma, Siyi Chen, Yu-Cheng Chou, Prakhar Kaushik, Alan Yuille
ECCV, 2026
[Paper] | [Code] | [Project Page] | [Dataset]
Benchmark for physically grounded scene reasoning, which decomposes scenes into objects with 84 fine-grained material, physical, affordance and function attributes, and reveals that VLMs struggle with multi-step property-driven reasoning.
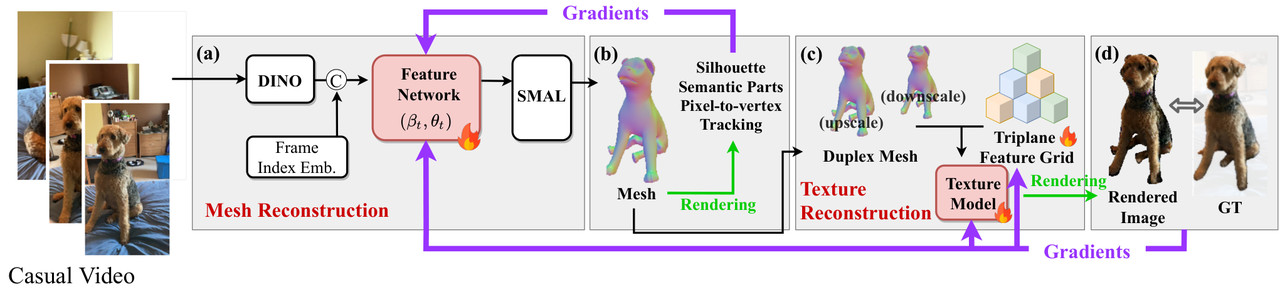
4D-Animal: Freely Reconstructing Animatable 3D Animals from Videos
Shanshan Zhong, Jiawei Peng, Zehan Zheng, Zhongzhan Huang, Wufei Ma, Guofeng Zhang, Qihao Liu, Alan Yuille, Jieneng Chen
WACV, 2026
[Paper] | [Code] | [Poster]
Keypoint-free framework for reconstructing animatable 3D animals from casual videos, which maps dense image features to SMAL parameters and enforces hierarchical silhouette, part-level, pixel-level and temporal alignment.
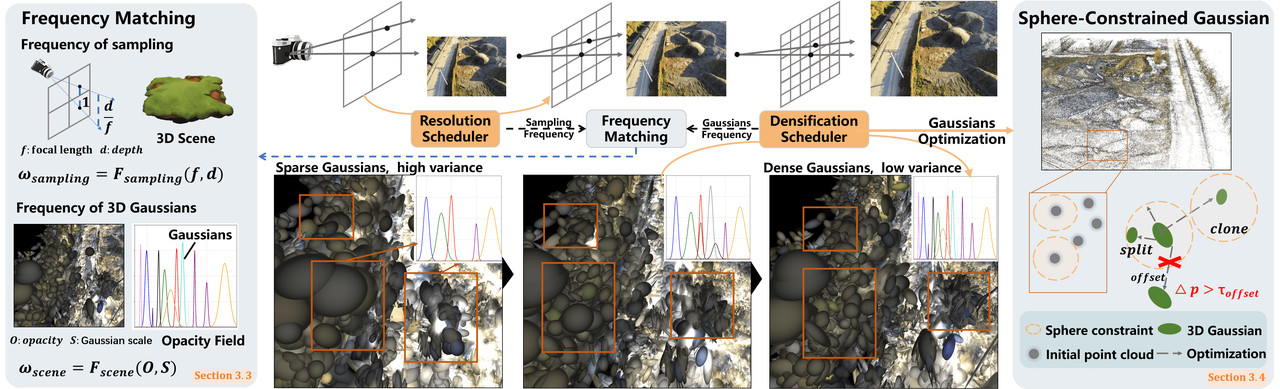
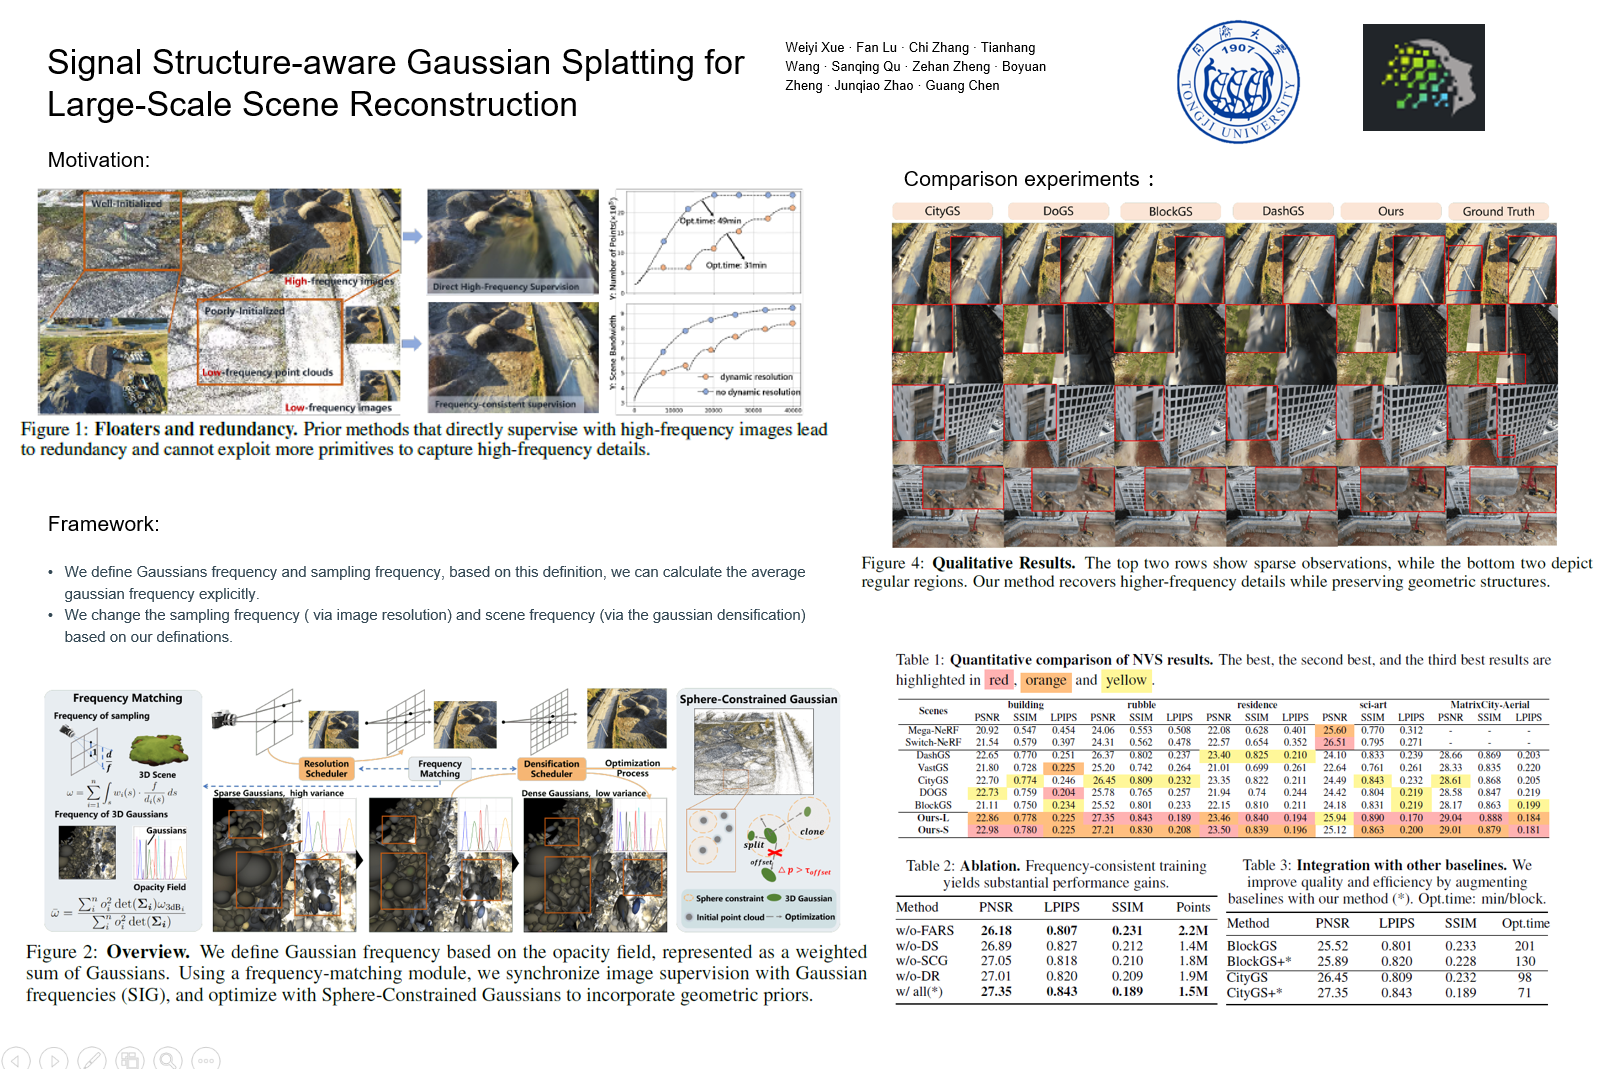
Signal Structure-Aware Gaussian Splatting for Large-Scale Scene Reconstruction
Weiyi Xue, Fan Lu, Chi Zhang, Tianhang Wang, Sanqing Qu, Zehan Zheng, Boyuan Zheng, Junqiao Zhao, Guang Chen
ICLR, 2026
[Paper] | [Code] | [Poster]
Frequency-aware scheduler for large-scale 3DGS reconstruction, which synchronizes image supervision with Gaussian frequencies and constrains Gaussians with point-cloud spatial priors for efficient and floater-free training.
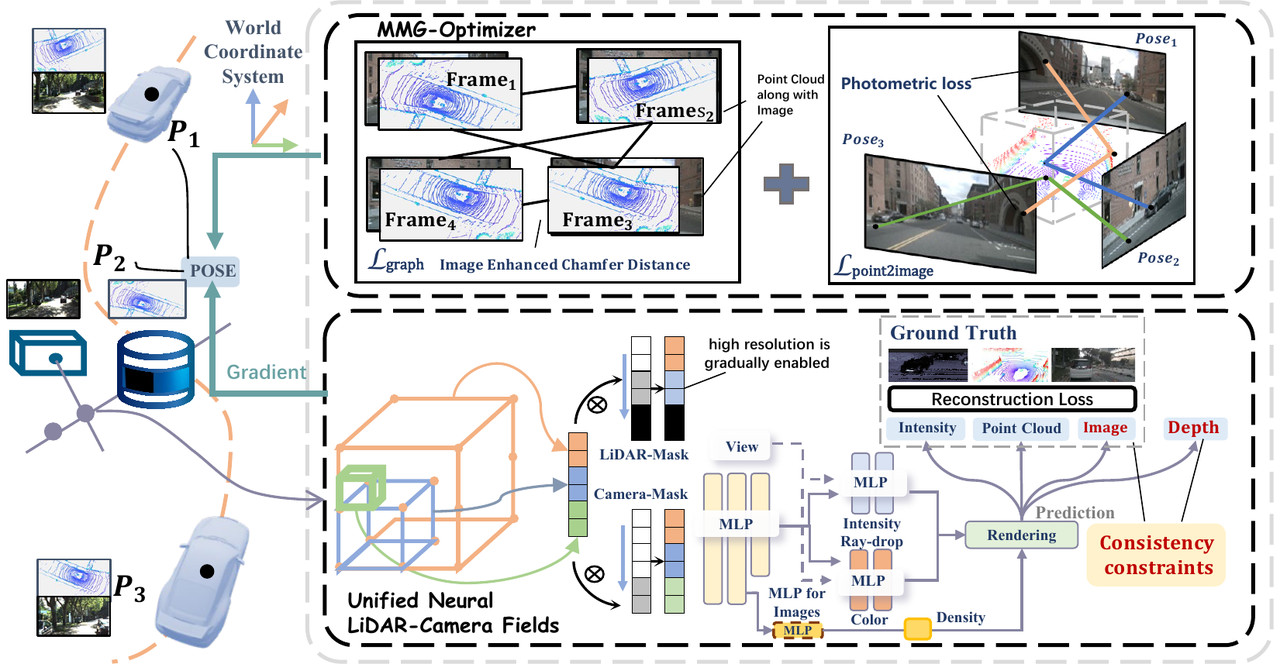
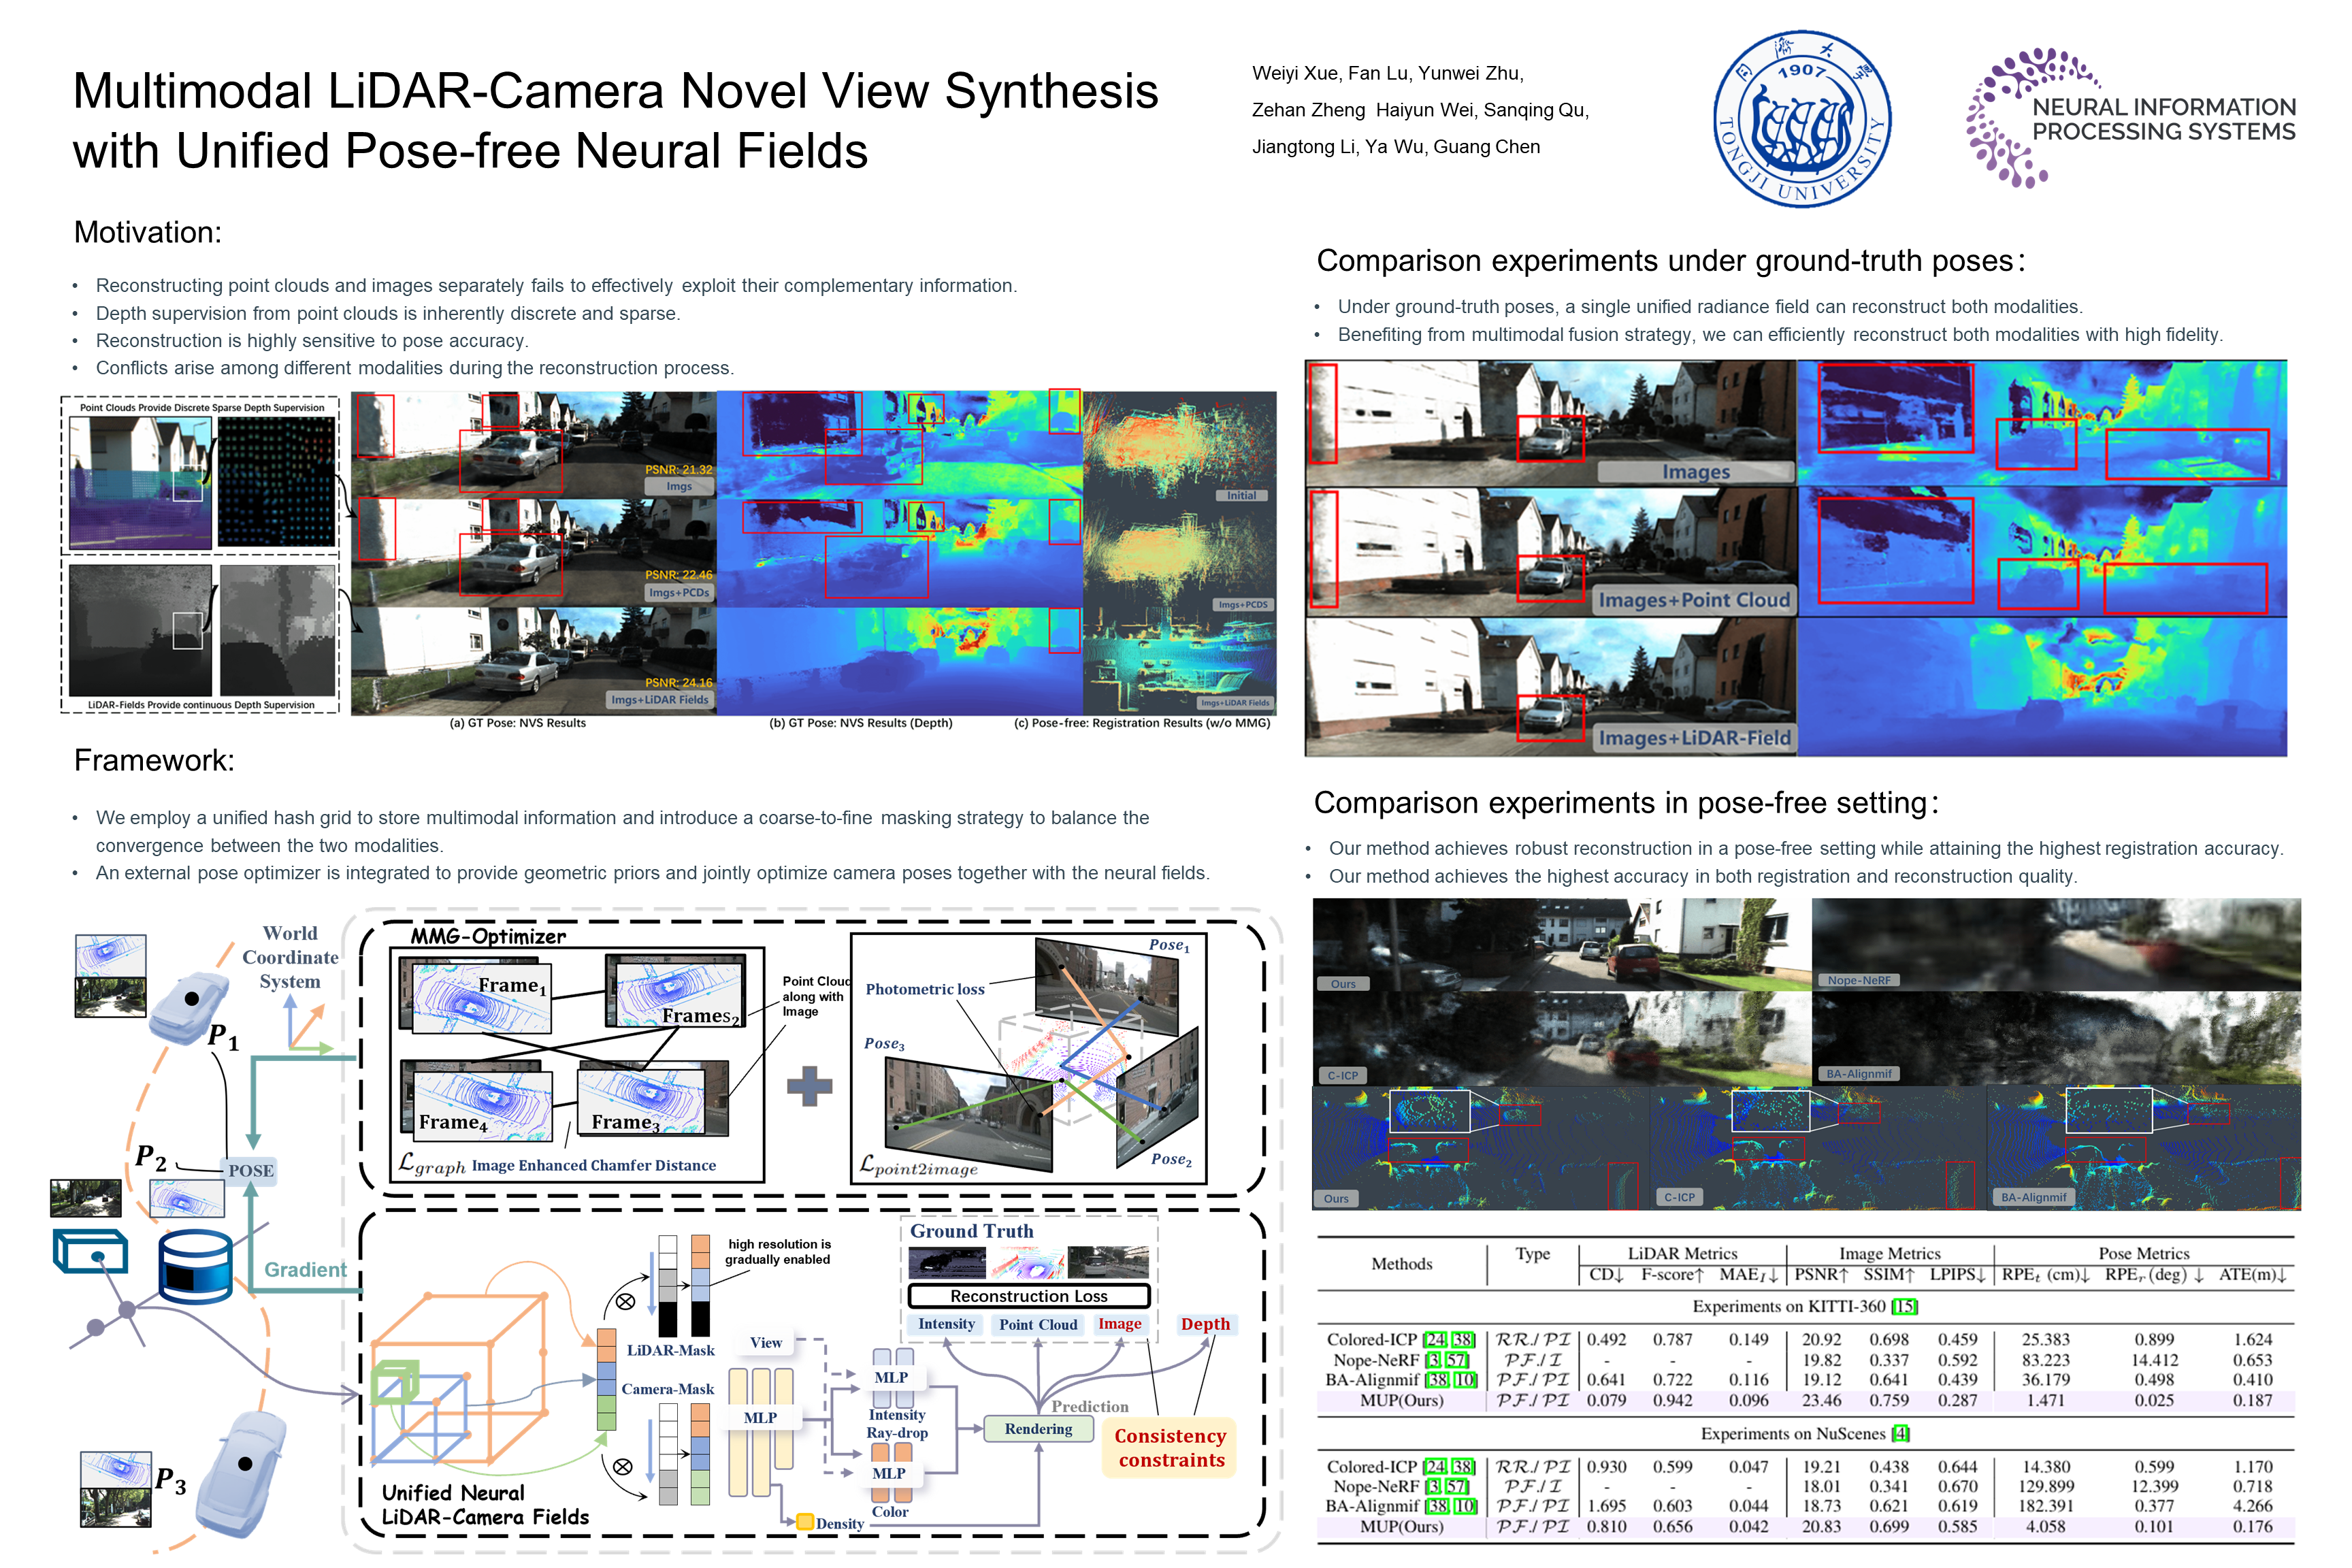
Multimodal LiDAR-Camera Novel View Synthesis with Unified Pose-free Neural Fields
Weiyi Xue, Fan Lu, Yunwei Zhu, Zehan Zheng, Sanqing Qu, Jiangtong Li, Ya Wu, Haiyun Wei, Guang Chen
NeurIPS, 2025
[Paper] | [Slides] | [Poster]
Unified pose-free neural field for joint LiDAR-camera novel view synthesis, which leverages both point-cloud geometry and image texture for pose optimization in large-scale driving scenes.
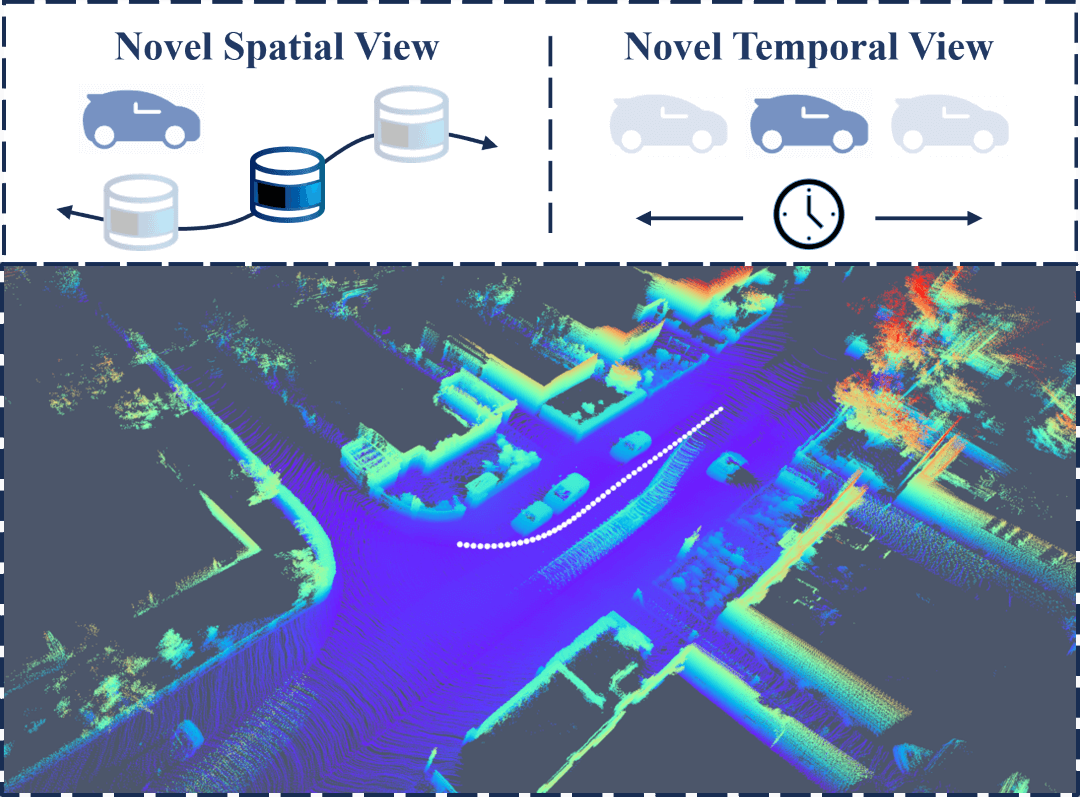
LiDAR4D: Dynamic Neural Fields for Novel Space-time View LiDAR Synthesis
Zehan Zheng, Fan Lu, Weiyi Xue, Guang Chen, Changjun Jiang.
CVPR, 2024
[Paper] | [Code] | [Project Page] | [Video] | [Talk] | [Slides] | [Poster]
Differentiable LiDAR-only framework for novel space-time LiDAR view synthesis, which reconstructs dynamic driving scenarios and generates realistic LiDAR point clouds end-to-end. It also supports simulation in the dynamic scene.
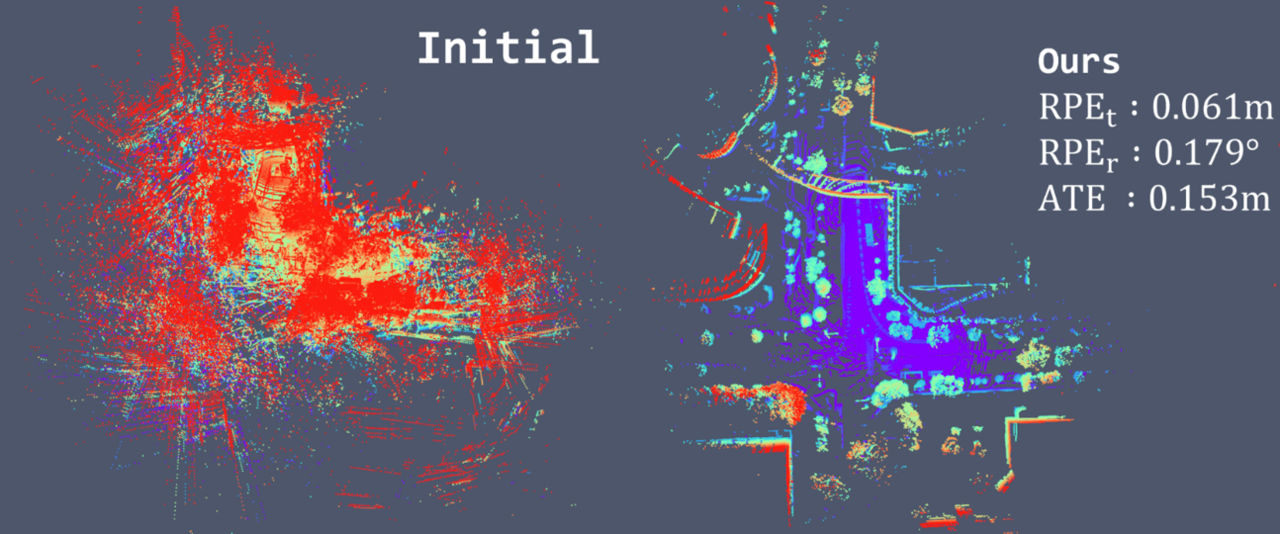
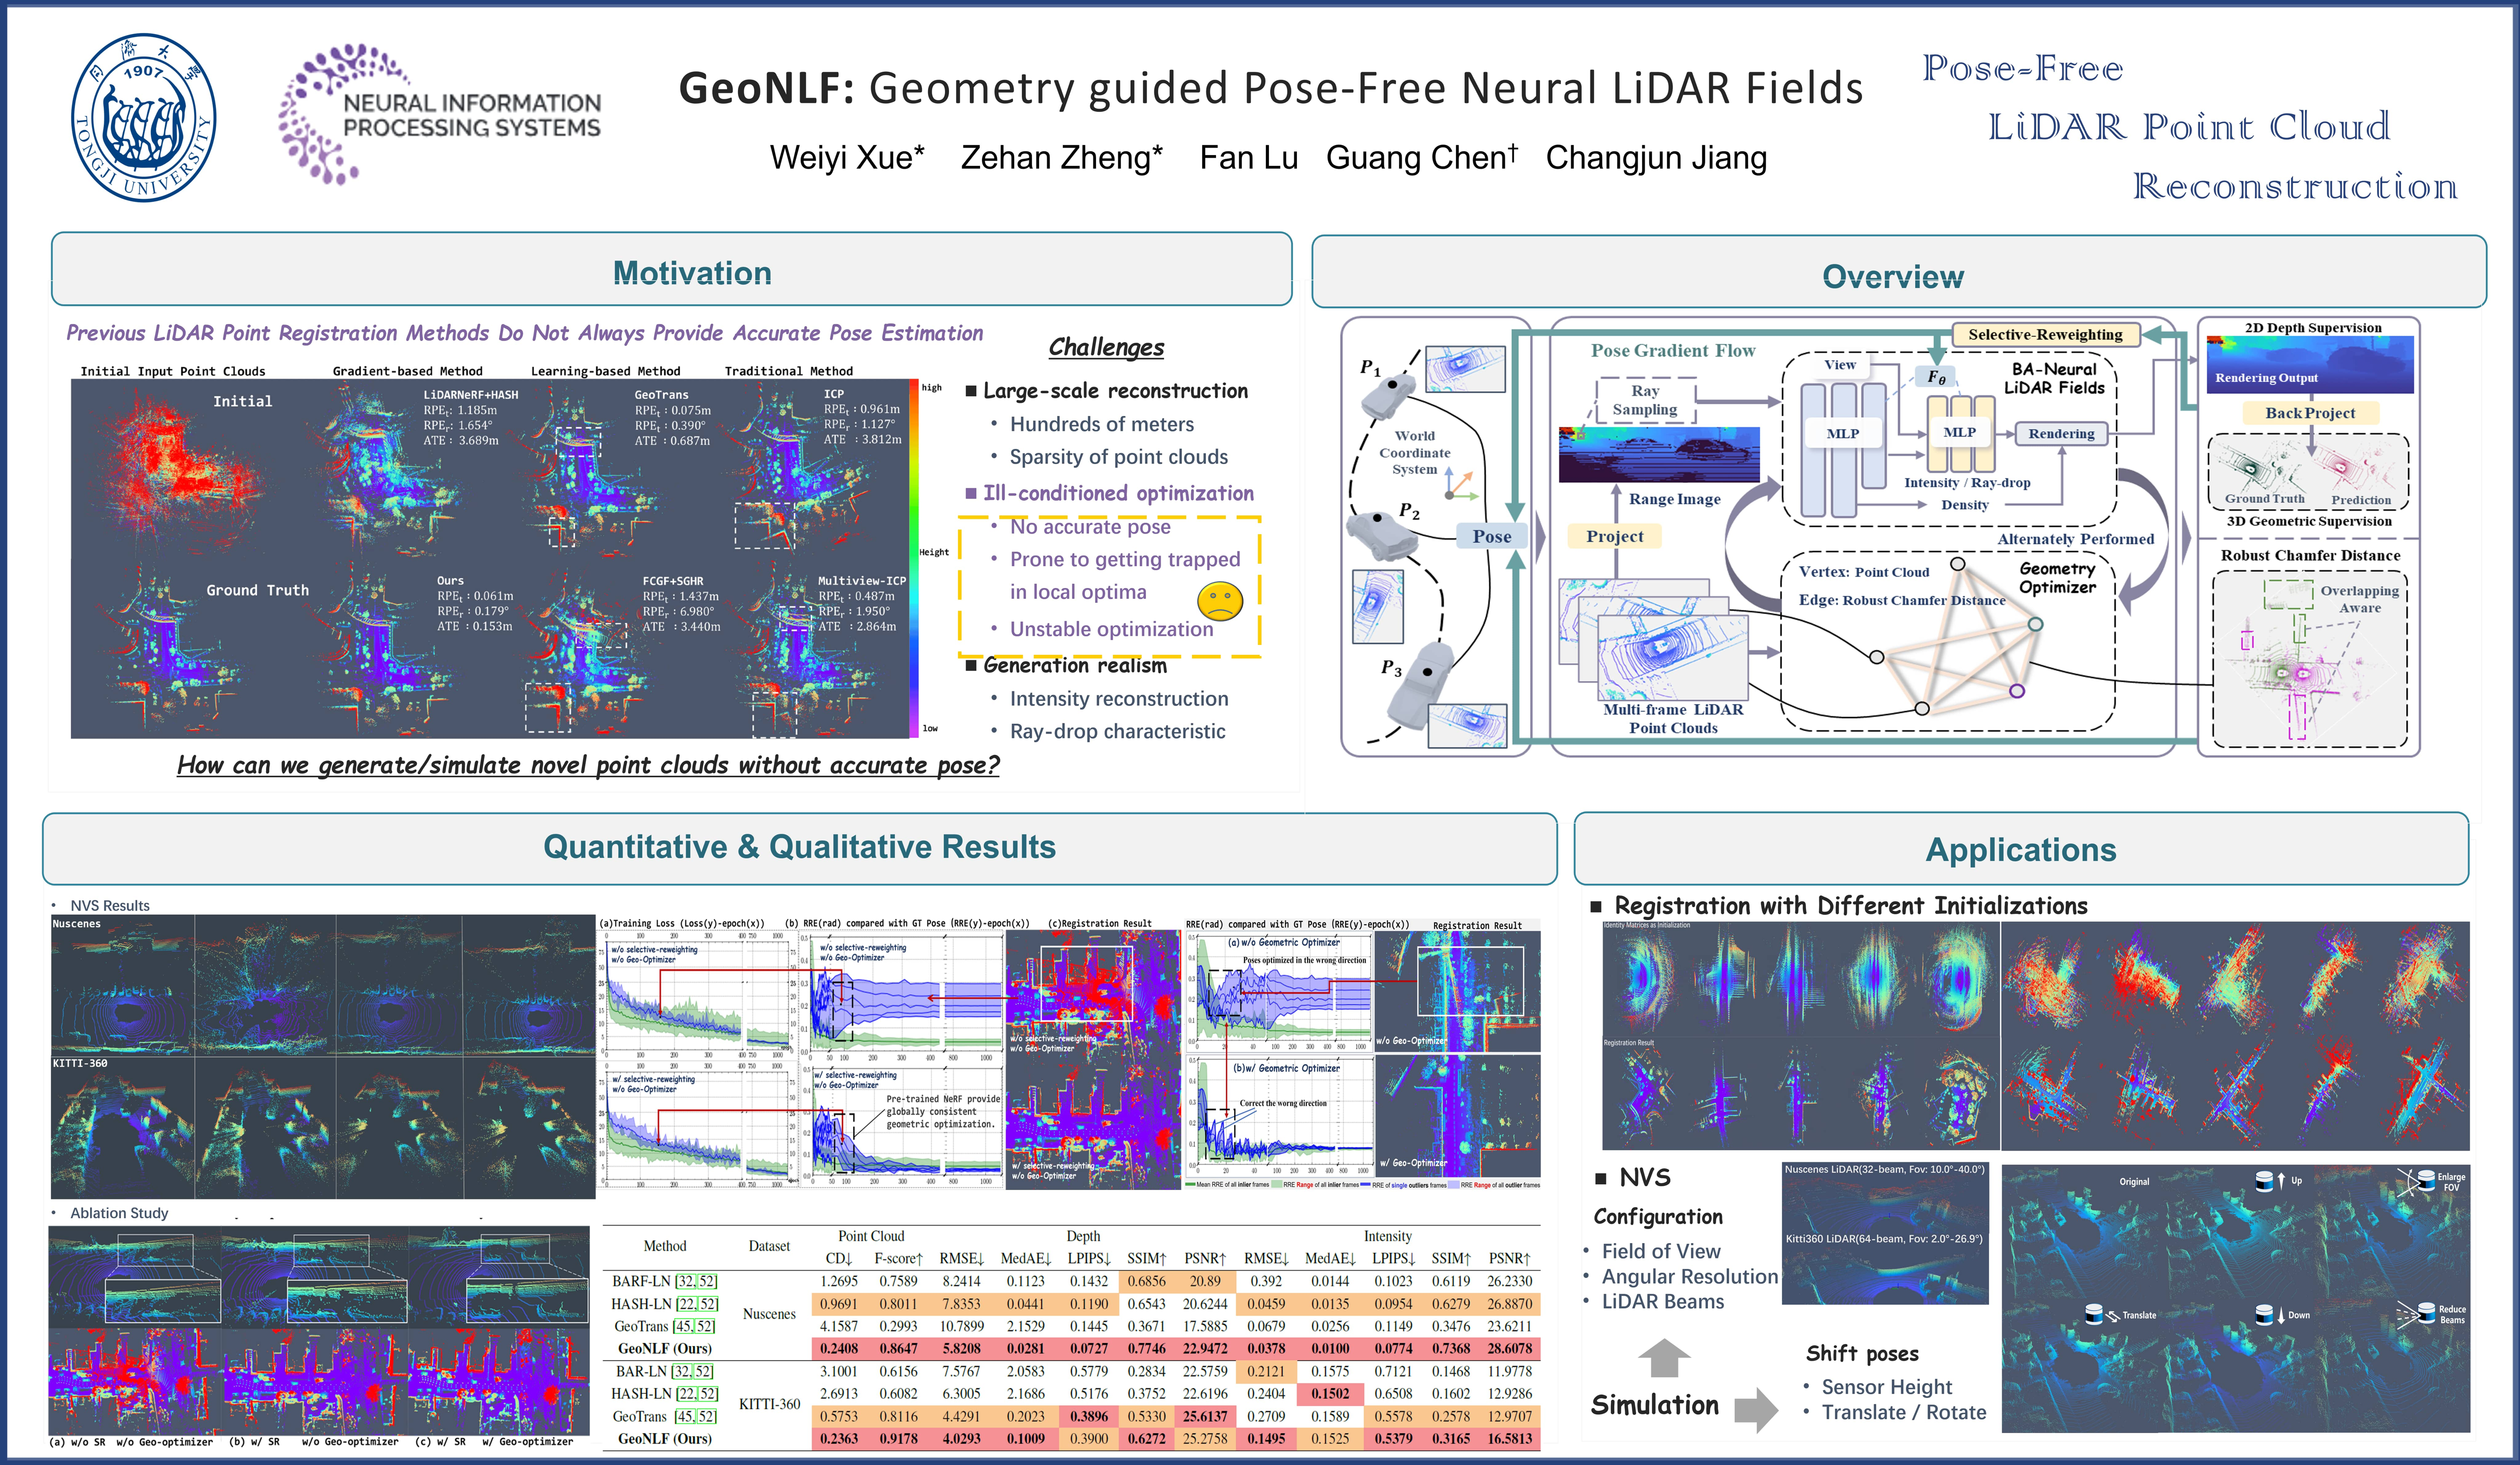
GeoNLF: Geometry-guided Pose-Free Neural LiDAR Fields
Weiyi Xue∗, Zehan Zheng∗, Fan Lu, Haiyun Wei, Guang Chen, Changjun Jiang
NeurIPS, 2024
[Paper] | [Code] | [Poster]
Global neural optimization framework for pose-free LiDAR reconstruction, which provides explicit geometric priors and achieve simultaneous large-scale multi-view registration and novel view synthesis.
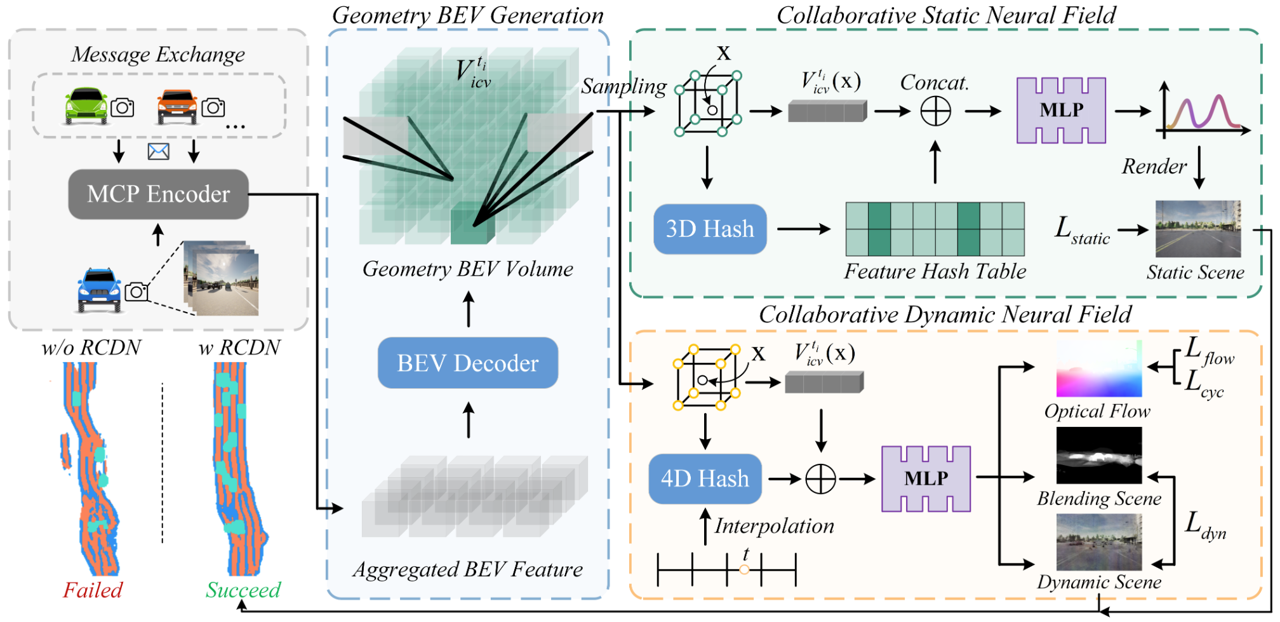
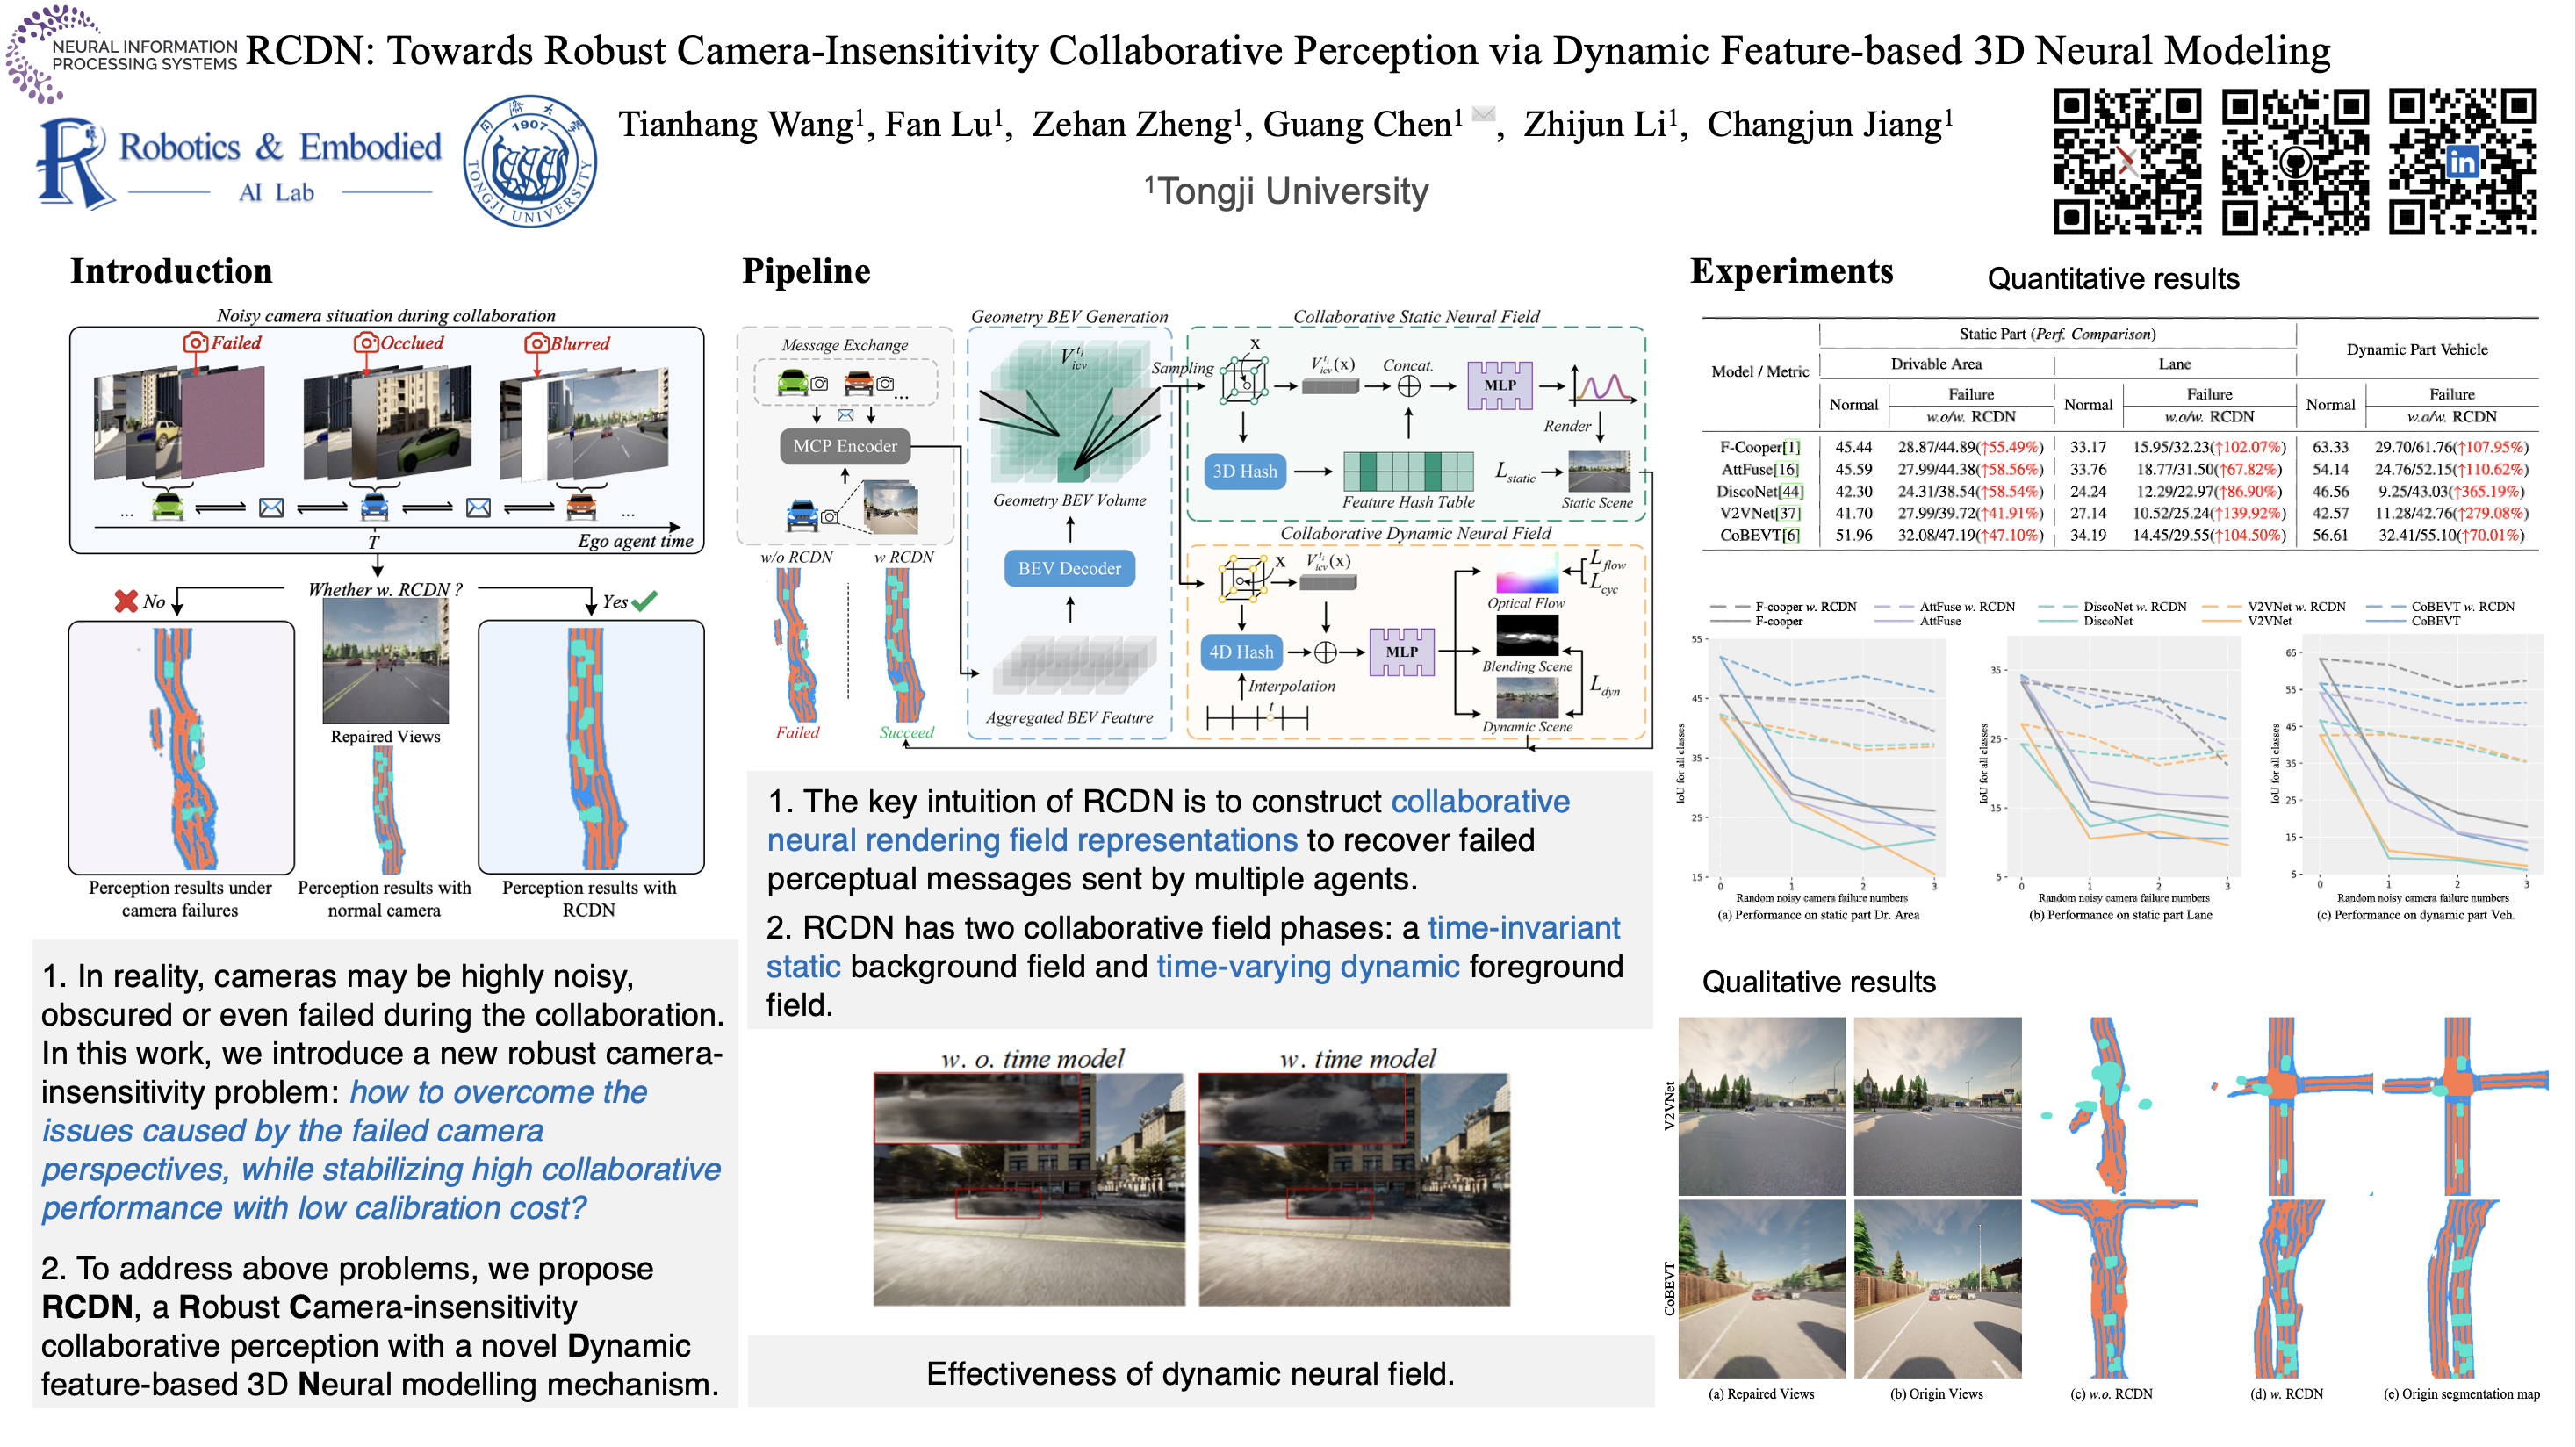
RCDN: Towards Robust Camera Insensitivity Collaborative Perception via Dynamic Feature-based 3D Neural Modeling
Tianhang Wang, Fan Lu, Zehan Zheng, Guang Chen, Changjun Jiang
NeurIPS, 2024
[Paper] | [Slides] | [Poster]
Collaborative perception framework with BEV feature based static and dynamic fields, which can recover failed perceptual messages sent by multiple agents and achieve high collaborative performance with low calibration cost.
NeuralPCI: Spatio-temporal Neural Field for 3D Point Cloud Multi-frame Non-linear Interpolation
Zehan Zheng∗, Danni Wu∗, Ruisi Lu, Fan Lu, Guang Chen, Changjun Jiang
CVPR, 2023
[Paper] | [Code] | [Project Page] | [Video] (6min)| [Talk] (15min) | [Slides] | [Poster]
4D spatio-temporal Neural field for 3D Point Cloud Interpolation, which implicitly integrates multi-frame information to handle nonlinear large motions for both indoor and outdoor scenarios.
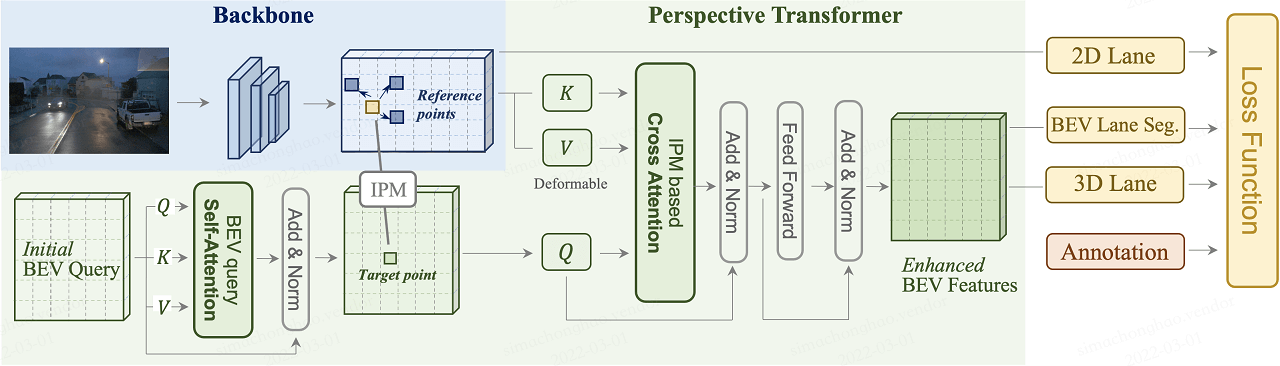
PersFormer: 3D Lane Detection via Perspective Transformer and the OpenLane Benchmark
Li Chen∗, Chonghao Sima∗, Yang Li∗, Zehan Zheng, Jiajie Xu, Xiangwei Geng, Hongyang Li, Conghui He, Jianping Shi, Yu Qiao, Junchi Yan.
ECCV, 2022 (Oral)
[Paper] | [Code] | [Blog] | [Slides] | [Video] (4min) | [Talk] (50min) | [Poster]
End-to-end monocular 3D lane detector with a novel Transformer-based spatial feature transformation module which generates BEV features by attending to related front-view local regions with camera parameters as a reference.
🏗️Projects
Vehicle-mounted Surround-view Fisheye Camera Panoramic Bird’s Eye View (BEV) Calibration
[GitHub Demo]
A novel calibration method for vehicle-mounted surround fish-eye cameras based on the drone, and a real-time bird’s eye view (BEV) generator.